MacLocalLLM · Tests and working notes
Local AI on our Macs.
We try image models, coding agents and local search on the machines we use. Here’s what worked, what didn’t, and when we still reached for the cloud.
Latest test · October 9, 2026
Qwen Image on two Macs and a Spark.
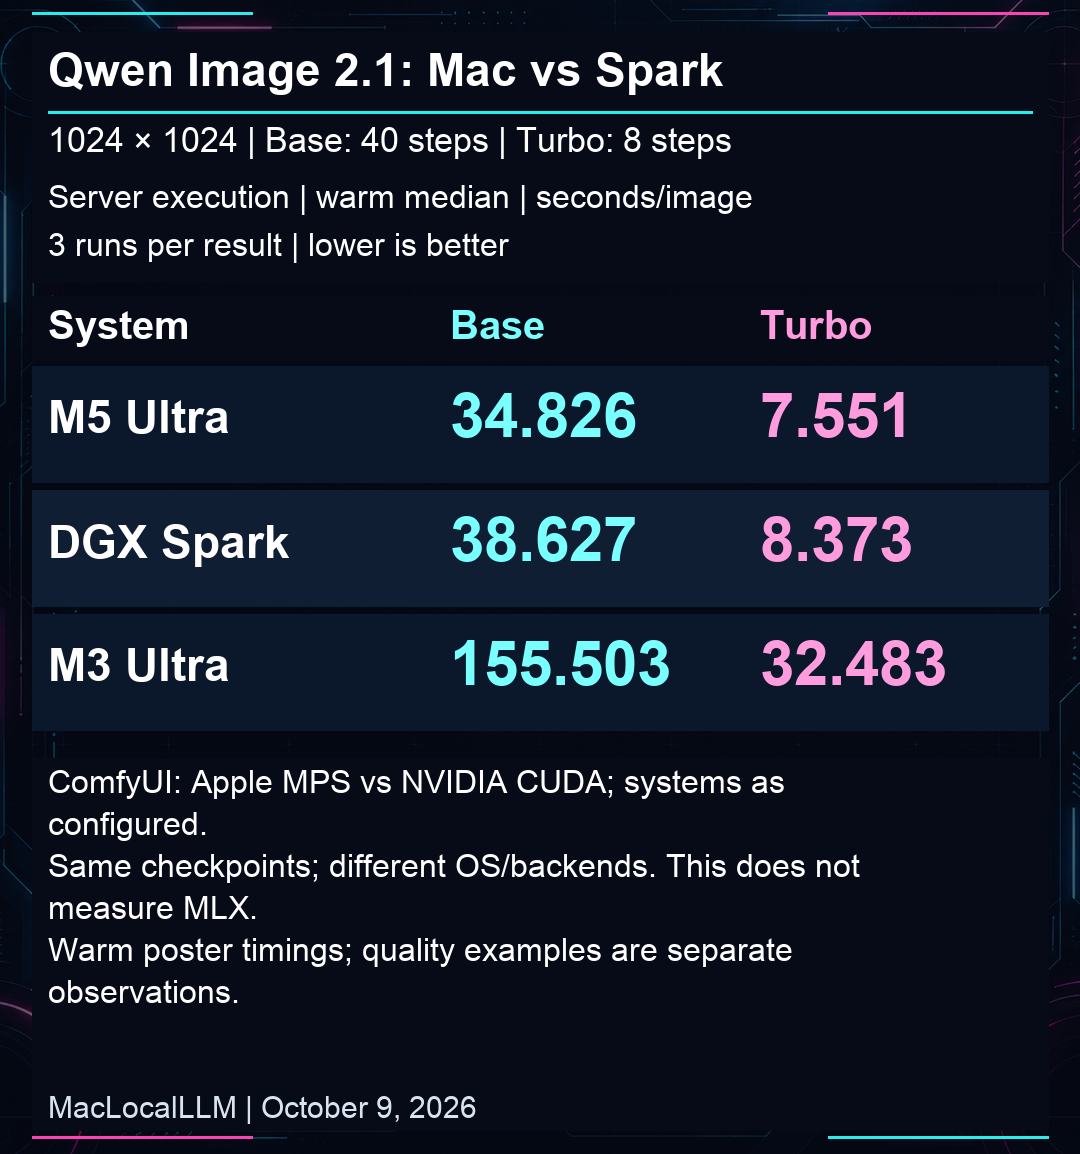
We gave the M3 Ultra, M5 Ultra and DGX Spark the same image prompts. Turbo took about eight seconds on the M5 and Spark, and 32 seconds on the M3.
The images were close across machines. The bigger difference was base versus Turbo: base kept more skin and fabric detail in our café example; Turbo looked smoother.
More from our setup
Pick a job. See what happened.
These are published tests and working notes you can read now.
Local search · Measured test
Is local search worth it?
We imported 769 documents on an M3 Ultra using two embedding models. The smaller model took 4.5 minutes; the larger one took 27.5. The cloud cost estimate was under three cents, so keeping it local needs a better reason than the API bill.
Read the embedding test →Coding agents · Measured test
Can a local model finish the coding job?
Five models got one small code change and a test to write. Four cloud models finished. The local 27B model didn’t. We show where it got stuck and why more room to read wasn’t enough.
See the coding results →Hermes agents · Field report
Same agent job, local or cloud?
We asked local Qwen, local Muse and DeepSeek Cloud to read a WordPress plugin inventory through Hermes. All three found the right count. Their waiting times and answer formats were quite different.
Read the agent comparison →Everyday use · Working notes
How we keep the work moving.
A task needs more than a prompt. These notes cover how we choose a model, give it a bounded job and check the result before calling it done. It’s our workflow, rather than another speed test.
Read the workflow notes →A little context
One result doesn’t tell the whole story.
A model can make good images and still struggle with a coding task. We keep those results separate, and explain what we actually asked it to do.
The setup matters.
We name the hardware, model and runner used. An MPS result and an MLX result are different tests, even on the same Mac.
We check the output.
For images, we look at the pictures. For coding, we inspect the change and run the tests. Finishing quickly isn’t much use if the result is wrong.
Small tests stay small.
Two image prompts or one agent job can help with a decision. They don’t make a universal ranking of models or machines.
Behind the site
Written and tested by ikeo1.
MacLocalLLM is published by IKEO Group. We write about the local AI work we do, including the times the Mac isn’t the quickest or most useful option.