Articles
Everything we have published, newest first.
Benchmarks, field reports and working notes on running local LLMs and local agents on Apple silicon. Each one carries the machine, the method, the settings and the failures.
-
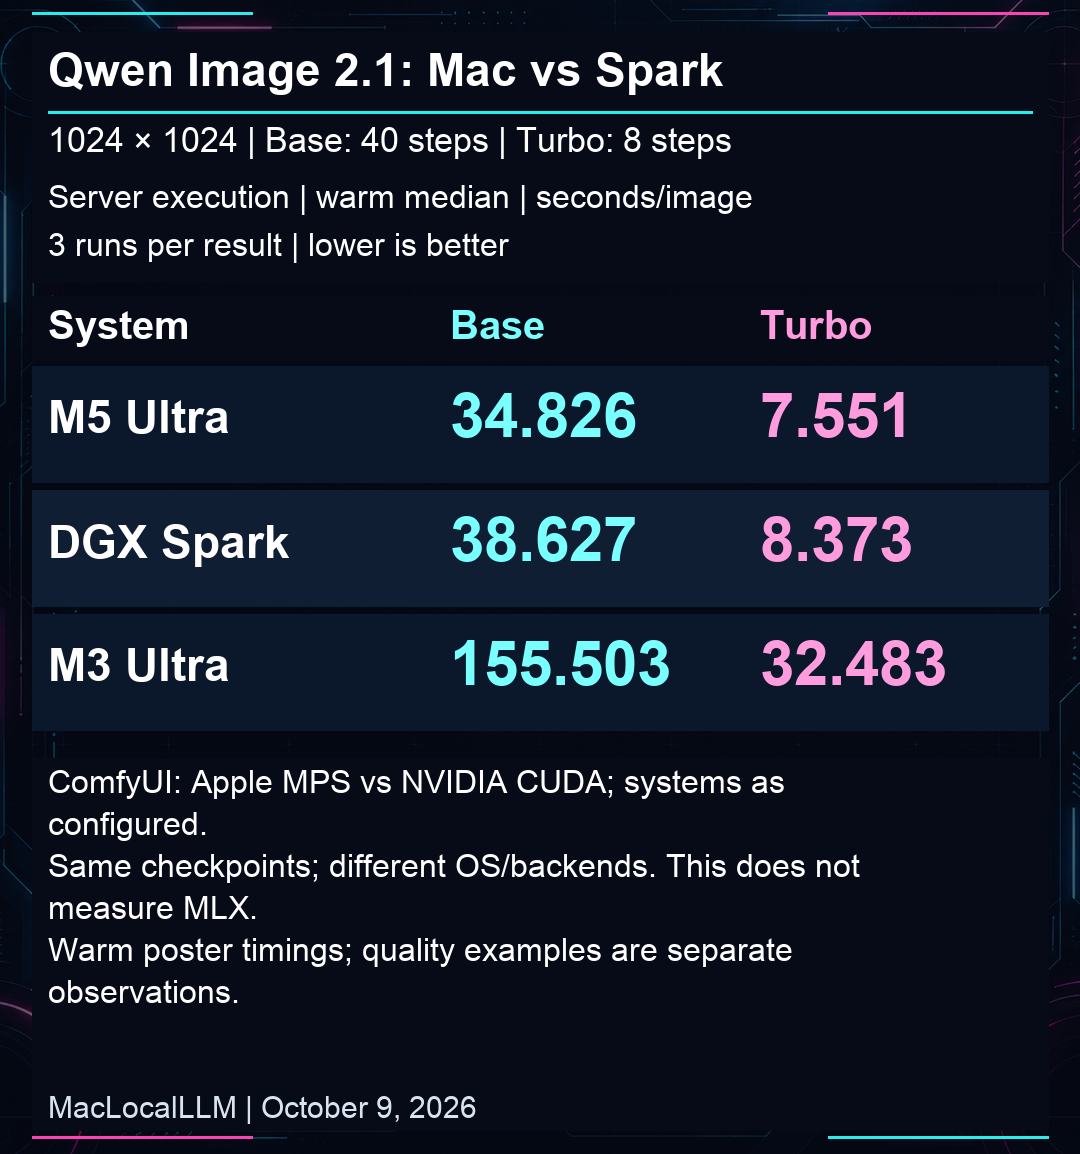
Qwen Image 2.1: M3 Ultra vs M5 Ultra vs DGX Spark
Turbo took about eight seconds on both the M5 Ultra and Spark. Here’s what we noticed after trying the same image prompts on all three machines.
-
I embedded my whole corpus locally. The cost argument is wrong.
Two full imports of 5,817 chunks on a Mac Studio M3 Ultra, with a small and a large embedding model. Six times the speed, a third of the disk, and…
-
How AI power users turn prompts into controlled workflows
A serious user delegates tasks; a power user designs and delegates workflows. The six-stage loop, the seven-layer tool stack, one complete WordPress launch — and why the routine work belongs…
-
Local LLM vs DeepSeek Cloud in a real Hermes agent job
One read-only WordPress inventory job through the same Hermes agent, run on local Qwen and Muse on a Mac Studio and on DeepSeek Cloud. What each model did, what it…
-
Five AI Models, One Coding Job: Where the Local Mac Fell Behind
Five models, one tightly bounded agentic coding job. Four cloud models finished in under 40 seconds; the local 27B on a Mac Studio did not finish. The method and every…
Methodology
What every result includes.
A tokens-per-second figure is only useful when you can understand and repeat the conditions behind it. Every result on this site carries all three of these.
01
The machine
Mac model, chip configuration, unified memory, storage, OS version and power mode.
02
The workload
Model identity, parameter size, quantization and source; runtime and version; context length, prompt, output length and settings.
03
The tradeoff
Speed, memory pressure, output quality, thermals, stability and whether the result was actually useful for the task.
Have a Mac we have not measured?
Bring it to the community.
Setups, results in progress and the arguments about them live on r/MacLocalLLM.